
Research Engineer (ML Engineering) – Berlin / London / Munich | Visa + Salary Insights
📍 Location: gb
🏷 Type: Not specified
Job Intelligence
📍 More in this location:
Browse AI jobs in gb
🏷 Similar roles:
🌐 Explore all jobs:
View all AI job listings
Job Overview
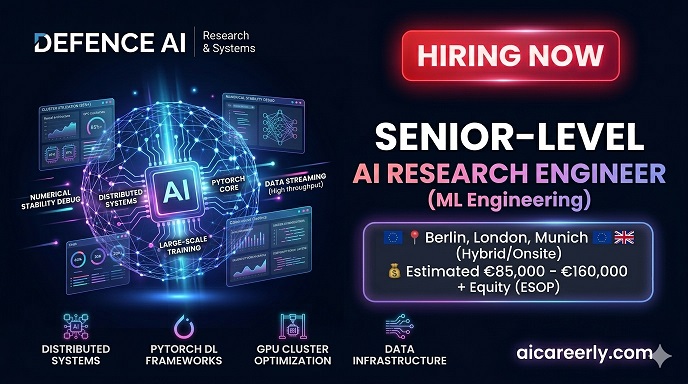
This role is for a Senior-Level AI Research Engineer (ML Engineering) at a high-impact European defence AI company focused on building next-generation systems for autonomous decision-making. The position sits at the intersection of machine learning research, distributed systems engineering, and large-scale model training infrastructure. The ideal candidate is a highly technical engineer with deep experience in PyTorch-based frameworks, scalable ML systems, and production-grade AI pipelines. You will contribute to mission-critical AI systems that support national security and democratic resilience, working alongside top-tier researchers and systems engineers in a fast-moving environment.
🌍 Work Eligibility & Location
- 🌍 Visa Sponsorship: Available for selected international candidates
- ✈️ Relocation Support: Yes, including financial relocation assistance
- 🏠 Remote Type: Hybrid / Onsite (Berlin, London, Munich)
- ⏰ Timezone Requirement: CET / GMT alignment preferred
- 🌐 Country Restrictions: Primarily EU/UK-friendly hiring scope
- 🗣️ Language Requirement: English
This is a highly international role with strong mobility support. While the core offices are in Europe, the company supports global talent acquisition with relocation pathways. The position is primarily Onsite/Hybrid, ensuring close collaboration across ML and systems engineering teams.
💰 Salary Intelligence
- 💰 Official Salary: Not publicly disclosed
- 📊 Estimated Range: €85,000 – €160,000 + equity (ESOP)
- 📈 Level: Senior-Level AI/ML Engineer
This compensation is highly competitive for the European AI defense sector, especially when combined with equity grants. The total package reflects the complexity of building scalable ML infrastructure and production-grade distributed training systems.
📊 Role Breakdown
This role focuses on building and scaling advanced ML infrastructure used for training large-scale models and reinforcement learning systems. Around 40% of your time will be spent extending PyTorch-based deep learning frameworks, improving usability and performance across teams. Another 30% focuses on scaling distributed training systems, ensuring GPU clusters are efficiently utilized and minimizing idle compute. You will also dedicate 20% to designing and optimizing data pipelines for large-scale datasets, ensuring high-throughput streaming and storage efficiency. The remaining 10% involves debugging production ML systems, identifying bottlenecks, and improving numerical stability and training reliability. Expect heavy use of Python, PyTorch, distributed systems tooling, and custom ML ops development at scale.
🧩 Required Skills & Fit
- ✅ Must: Advanced Python engineering experience
- ✅ Must: Strong ML/DL expertise with PyTorch / JAX / TensorFlow
- ✅ Must: Experience with distributed training systems
- ➕ Bonus: GPU cluster optimization (NCCL, MPI)
- ➕ Bonus: Large-scale dataset engineering & streaming systems
📈 Difficulty & Competitiveness
- ⚡ Level: Very High
- 📊 Experience barrier: 5+ years
- 🧠 Skill complexity: Advanced systems + ML hybrid engineering
- 🌍 Competition: Extremely competitive (top-tier AI engineers globally)
This is a top-tier engineering role requiring both deep theoretical ML understanding and strong systems engineering capability. Candidates are expected to operate at production scale with minimal supervision.
🚀 Career Impact
- ⭐ Impact Rating: ⭐⭐⭐⭐⭐
- 🏢 Brand value: Leading European defence AI company
- 📚 Skill growth: Frontier ML systems + distributed AI infrastructure
- 🚀 Future opportunities: Staff AI Engineer, Research Lead, Infra Architect
This role provides significant long-term value, positioning engineers at the frontier of defence-grade AI systems and large-scale model training. Experience gained here translates directly into leadership roles across top AI labs and infrastructure companies.
📋 Key Responsibilities
You will design and extend ML frameworks built on PyTorch, ensuring they scale across distributed GPU clusters. A major responsibility includes improving training throughput and optimizing memory and compute efficiency across large-scale systems. You will also build and maintain distributed training pipelines, ensuring high reliability and reproducibility. Another key responsibility is developing data infrastructure strategies for large datasets, including streaming, encoding, and storage optimization. Additionally, you will debug production ML pipelines, identify performance bottlenecks, and resolve numerical stability issues in large-scale training environments.
🎯 Application Strategy
- 🎯 Best apply method: Direct company application portal
- 🔥 Highlight: Distributed training systems experience
- 🔥 Highlight: PyTorch customization & performance tuning
- ❌ Avoid: Generic ML project descriptions without scale
- ❌ Avoid: Overemphasis on academic theory without systems depth
🧠 Application Optimization (Adaptive)
This section should be tailored based on your experience level and used to optimize alignment with the role requirements.
AI Research Engineer (ML Engineering) focused on distributed training systems, PyTorch frameworks, and large-scale ML infrastructure.Candidate:
[Paste CV]
Optimize for this role.
Focus:
Signal strength
Role alignment
Missing high-impact elements
🧠 Fit & Positioning Analysis
Evaluate your profile critically before applying to ensure alignment with senior-level ML infrastructure expectations.
Match score against senior ML engineering benchmark
Strengths in distributed systems and ML frameworks
Technical gaps in GPU scaling or data pipelines
Positioning improvements for stronger candidacy
📅 Application Signals
This role signals strong demand for senior ML infrastructure engineers in Europe’s defence AI ecosystem. Competition is extremely high due to limited openings and high technical barriers. Candidates with distributed training experience and GPU optimization expertise are prioritized heavily in screening stages.
🚀 Resume Optimization for This Role
⚡ Takes less than 2 minutes — optimize specifically for this position before applying
🎯 0/5 completed
Tailoring your CV to this exact role significantly increases your chances.
✅ Ready to apply — your profile is aligned with this role
🔗 Apply for this Job
✅ Job Source & Verification
This job post is derived from official Helsing career documentation, reflecting a high-credibility primary source. Last updated information aligns with 2026 hiring cycle requirements, ensuring accuracy in role expectations, compensation structure, and technical responsibilities.
Similar Jobs
Lead Software Developer (AI Solutions) – Oxford, UK | Visa + Salary Insights
Location: gb
Type: Full-time

AI/ML Postdoctoral Fellow – London (Francis Crick Institute) | Visa + Salary Insights
Location: gb
Type: Full-time

Machine Learning Manager – Fincrime (Fraud) – London / Cardiff / Remote UK | Visa + Salary Insights
Location: gb
Type: Full-time