
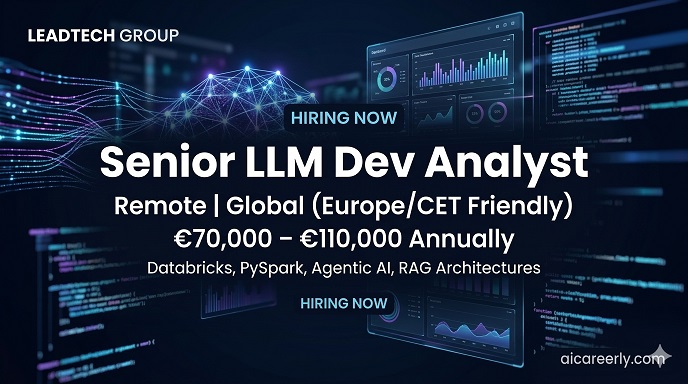
Senior LLM Dev Analyst – Remote Spain | Visa + Salary Insights
📍 Location: eu
🏷 Type: Not specified
Job Intelligence
📍 More in this location:
Browse AI jobs in eu
🏷 Similar roles:
🌐 Explore all jobs:
View all AI job listings
Job Overview
This role is for a Senior-Level (5+ years) LLM Dev Analyst focused on building intelligent, production-grade AI agents inside a Databricks ecosystem. The company is looking for a candidate who can bridge Large Language Models (LLMs), data engineering, and business analytics to automate decision-making across marketing, experimentation, and internal data workflows. The ideal professional is someone who can design scalable AI systems using Python, PySpark, and modern agent frameworks, while also understanding real-world business impact in areas like A/B testing and MarTech optimization.
🌍 Work Eligibility & Location
- 🌍 Visa Sponsorship: Not explicitly stated
- ✈️ Relocation Support: Possible for Barcelona office, not guaranteed
- 🏠 Remote Type: Remote or hybrid (Barcelona office optional)
- ⏰ Timezone Requirement: Likely Europe-friendly (CET)
- 🌐 Country Restrictions: None specified
- 🗣️ Language Requirement: English (working proficiency expected)
This position is highly accessible for global talent due to its Remote flexibility. While Spain is listed as the base, the structure suggests international hiring is possible. However, lack of explicit visa sponsorship means candidates outside the EU should clarify relocation policies before applying.
💰 Salary Intelligence
- 💰 Official Salary: Not disclosed
- 📊 Estimated Range: €70,000 – €110,000 annually
- 📈 Level: Senior-Level
Given the stack complexity involving LLMs, Databricks, and production AI systems, this role sits in a high-value engineering bracket. Similar European AI engineering roles with agentic AI responsibilities typically command competitive compensation, especially when tied to analytics, experimentation, and scalable ML infrastructure.
📊 Role Breakdown
This role sits at the intersection of applied AI and enterprise data engineering. You will design and deploy LLM-powered agents capable of performing multi-step reasoning across structured and unstructured data. Core work revolves around building intelligent systems using Databricks, integrating PySpark pipelines, and enabling real-time analytics automation. A major focus is implementing RAG (Retrieval-Augmented Generation) systems that connect LLMs with enterprise datasets, ensuring contextual accuracy and reduced hallucination risk.
On the engineering side, you will build scalable workflows using Python, SQL, and Databricks Jobs. On the AI side, you will design prompts, evaluation frameworks, and guardrails to ensure reliability and measurable performance. Expect to optimize agent workflows for marketing analytics, experimentation insights, and data engineering automation. A strong emphasis is placed on improving decision velocity by at least 30–50% through automation and intelligent orchestration systems.
🧩 Required Skills & Fit
- ✅ Must: Large Language Models (LLMs) development
- ✅ Must: Prompt engineering & RAG architectures
- ✅ Must: Python, SQL, PySpark
- ➕ Bonus: Databricks, Snowflake, or GCP
- ➕ Bonus: LangChain, LlamaIndex, or agent frameworks
📈 Difficulty & Competitiveness
- ⚡ Level: High
- 📊 Experience barrier: 5+ years
- 🧠 Skill complexity: Advanced (AI systems + data engineering)
- 🌍 Competition: Global (highly competitive AI talent pool)
This is a technically demanding role requiring strong depth in both LLM systems and enterprise data infrastructure. Candidates without production experience in AI systems, especially with Databricks or RAG pipelines, will face significant difficulty competing.
🚀 Career Impact
- ⭐ Impact Rating: ⭐⭐⭐⭐⭐
- 🏢 Brand value: Strong European AI/MarTech company
- 📚 Skill growth: Advanced LLM engineering & agent systems
- 🚀 Future opportunities: AI Architect, Head of AI, Staff Engineer
This role provides strong upward mobility into AI architecture and senior machine learning engineering leadership. Exposure to production-grade agent systems and enterprise data stacks significantly increases long-term career value in the global AI job market.
📋 Key Responsibilities
You will be responsible for designing and deploying LLM-powered agents that automate analytics and business workflows. This includes building RAG pipelines to connect enterprise data with generative AI systems and implementing scalable data workflows using Databricks, PySpark, and SQL. A major part of the role involves optimizing prompts and designing evaluation frameworks to ensure model accuracy and consistency.
You will also develop automation systems for A/B testing analysis, marketing performance reporting, and data engineering operations. Beyond engineering, you will collaborate with cross-functional teams to translate business requirements into AI-driven solutions. Ensuring system reliability through monitoring, logging, and guardrails is also a critical responsibility.
🎯 Application Strategy
- 🎯 Best apply method: Highlight production AI systems experience
- 🔥 Highlight: RAG pipelines
- 🔥 Highlight: Databricks + PySpark scaling
- ❌ Avoid: Overemphasis on academic ML only
- ❌ Avoid: Generic Python-only projects
🧠 Application Optimization (Adaptive)
This section is personalized by seniority.
How to use: Paste into ChatGPT, Claude, or Gemini
LLM Dev Analyst building AI agents in Databricks for analytics, marketing automation, and data workflows.Candidate:
[Paste CV]
Optimize for this role.
Focus:
Signal strength
LLM production experience
Databricks + RAG expertise
Missing high-impact elements
🧠 Fit & Positioning Analysis
Evaluate your match before applying. This role strongly favors candidates with proven production LLM systems, especially those integrating enterprise data pipelines. Strong alignment exists if you have experience in AI automation, analytics engineering, or agent-based architectures.
Match score
Strengths
Gaps
Positioning improvements
📅 Application Signals
This is a high-demand AI engineering role with strong competition due to its focus on LLM agents and enterprise-scale data systems. Early applicants with relevant Databricks or RAG experience are more likely to progress quickly through screening.
🚀 Resume Optimization for This Role
⚡ Takes less than 2 minutes — optimize specifically for this position before applying
🎯 0/5 completed
Tailoring your CV to this exact role significantly increases your chances.
✅ Ready to apply — your profile is aligned with this role
🔗 Apply for this Job
✅ Job Source & Verification
This listing is sourced from an official Leadtech Group recruitment post, a recognized European digital and software company. The information reflects the latest publicly available job description as of the most recent posting update. Always verify final details on the official careers page before applying.
Similar Jobs
JustHealth PhD Researcher (AI in Healthcare Ethics & Cardiology) – Leuven, Belgium | Visa + Salary Insights
Location: eu
Type: Full-time
Scientific Collaborator in AI-Enabled Precision Health – Lugano, Switzerland | Visa + Salary Insights
Location: eu
Type: Full-time
Assistant/Associate Professor in Embedded & Distributed AI – Palaiseau, France | Academic Salary Insights
Location: eu
Type: Contract
PhD Position in AI-Supported Transport Infrastructure Resilience – Zurich | Visa + Salary Insights
Location: eu
Type: Full-time
Postdoctoral Researcher in Machine Learning for Electric Vehicle Fleet Coordination – Gothenburg, Sweden | Visa + Salary Insights
Location: eu
Type: Full-time
Tech Lead LLM & Generative AI – Norway (Remote) | Visa + Salary Insights
Location: eu
Type: Full-time